
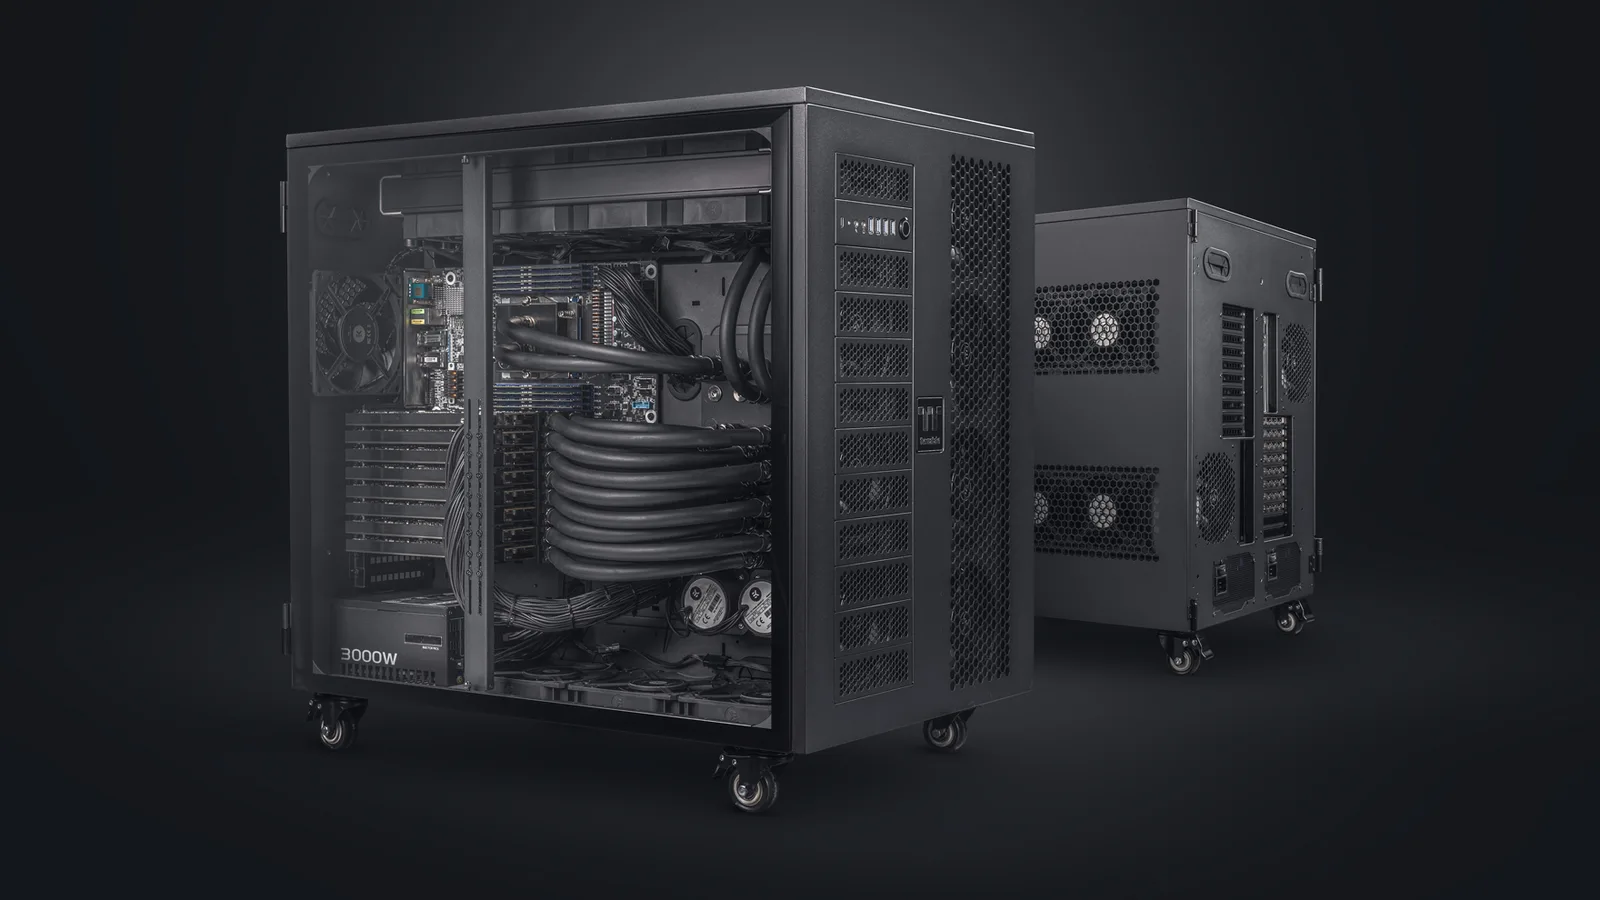
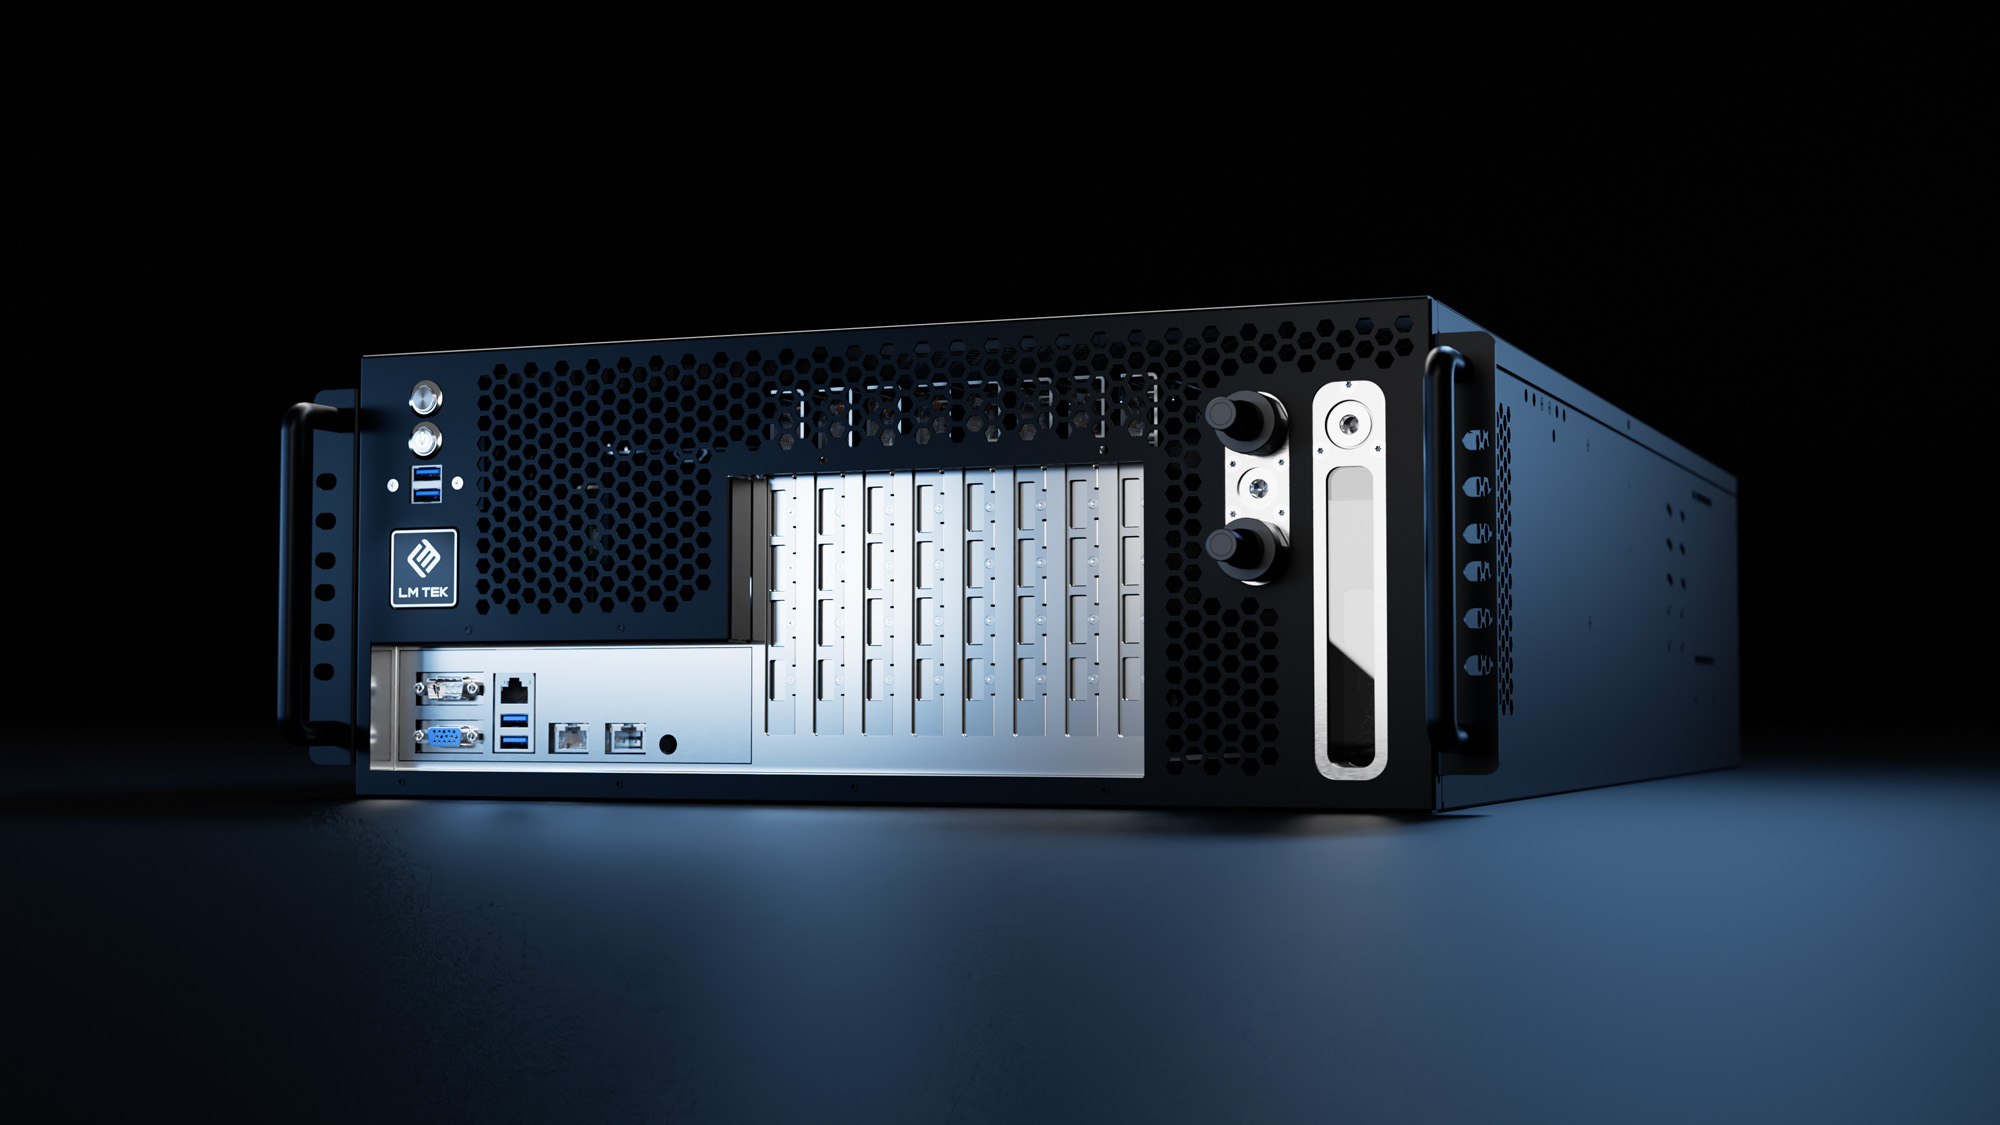
Match the platform to the workload.
The workload determines the populated configuration. Reference configurations illustrate a scale; they do not promise application performance.
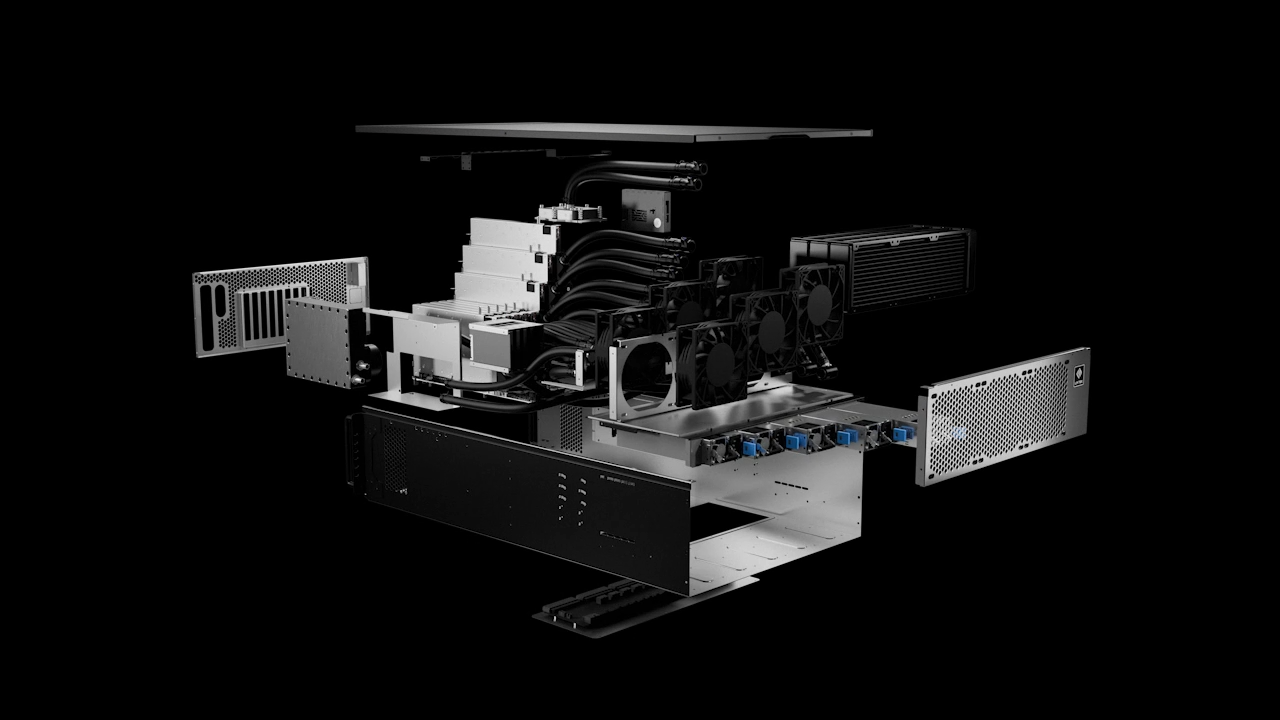
A barebone platform: LM TEK supplies the chassis, the integrated cooling loop, and platform-level power. You specify the board, CPUs, GPUs, memory, and storage.
Compute-heavy work, kept in the building.
-
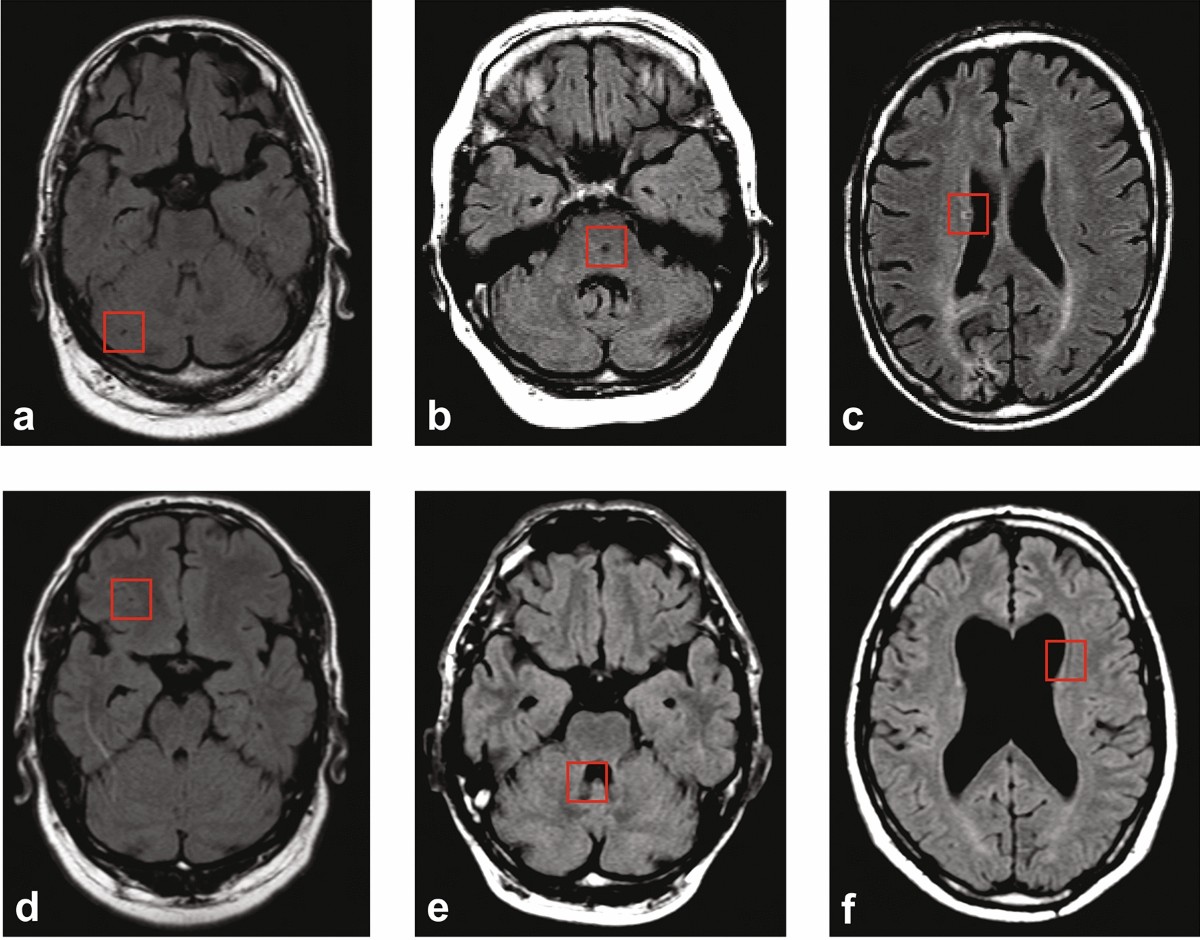
Medical imaging
Volumetric reconstruction and AI-assisted diagnostics, next to the data.
-
Scientific visualisation
Simulation output rendered where the dataset lives.
-
CAD & CAM
Solver and simulation runs behind the design team.
-
Video post-production
Shared GPU capacity for rendering, encoding and grading.
-
Computational research
Dense single-node HPC and training workloads.
Four workloads, one platform.
-
01
Private LLM inference
Size local inference around the model, concurrency and data requirements.
- Reference scale
- Modest start · Departmental AI / single-team inference
- Mid-tier · Research group / multi-user inference / light fine-tuning
- Production maximum · Enterprise inference / production fine-tuning
-
02
Fine-tuning
Discuss memory capacity, accelerator support and the intended training workflow.
- Reference scale
- Mid-tier · Research group / multi-user inference / light fine-tuning
- Production maximum · Enterprise inference / production fine-tuning
-
03
Simulation and HPC
Start with the solver, data movement and compute requirements.
Configure a system → -
04
Rendering
Check renderer support and the balance between GPU capacity, CPU work and storage.
Configure a system →
Three reference scales.
The chassis, the integrated cooling loop, and platform-level power arrive engineered as one system; the board, CPUs, GPUs, memory, and storage are specified per deployment. One chassis carries a configuration from a two-GPU entry build to eight accelerators at up to 700 W per slot.
| Tier | Reference configuration | Use case |
|---|---|---|
| Modest start | 2× RTX 6000 Ada · 1× EPYC 9354 · 256 GB DDR5 ECC | Departmental AI / single-team inference |
| Mid-tier | 4× RTX PRO 6000 Blackwell · 2× EPYC 9474F · 512 GB DDR5 ECC | Research group / multi-user inference / light fine-tuning |
| Production maximum | 8× NVIDIA H200 NVL · 2× Xeon Platinum 8580 · 1 TB DDR5 ECC | Enterprise inference / production fine-tuning |
Reference configurations are examples drawn from real customer builds, not a fixed bill of materials. The final BOM is specified per deployment; a configuration inside the published validation specs is quotable as is, and LM TEK engineering is available for anything outside them.
Sizing a first deployment?
The buying guide covers how to start small without throwing early spend away.
The workload determines the populated configuration.
Describe the model, solver or renderer and the data it works on; an engineer sizes the configuration with you.
Understand the application with AI Solutions →